Which AI Tools Are Actually Worth Trying?

An AI writing tool turned a straightforward support note into confident but inaccurate instructions, and I did not catch the errors until a coworker reviewed it. I need to decide whether to keep testing AI tools for routine writing, research, and document cleanup or stop spending time on them. The hard part is that I can only evaluate them in short gaps during my workday, so tools that need extensive setup or constant fact-checking are not practical.

Which AI tools have been genuinely useful in regular work without creating more review work than they save, and what kind of task showed you they were worth trying?

One Tool Isn’t the Answer

The thing most people get wrong about AI tools is assuming one app should handle everything. I’ve had better results picking a tool for the job in front of me. General assistants are useful, but document review, translation, coding, video, and automation have different needs.

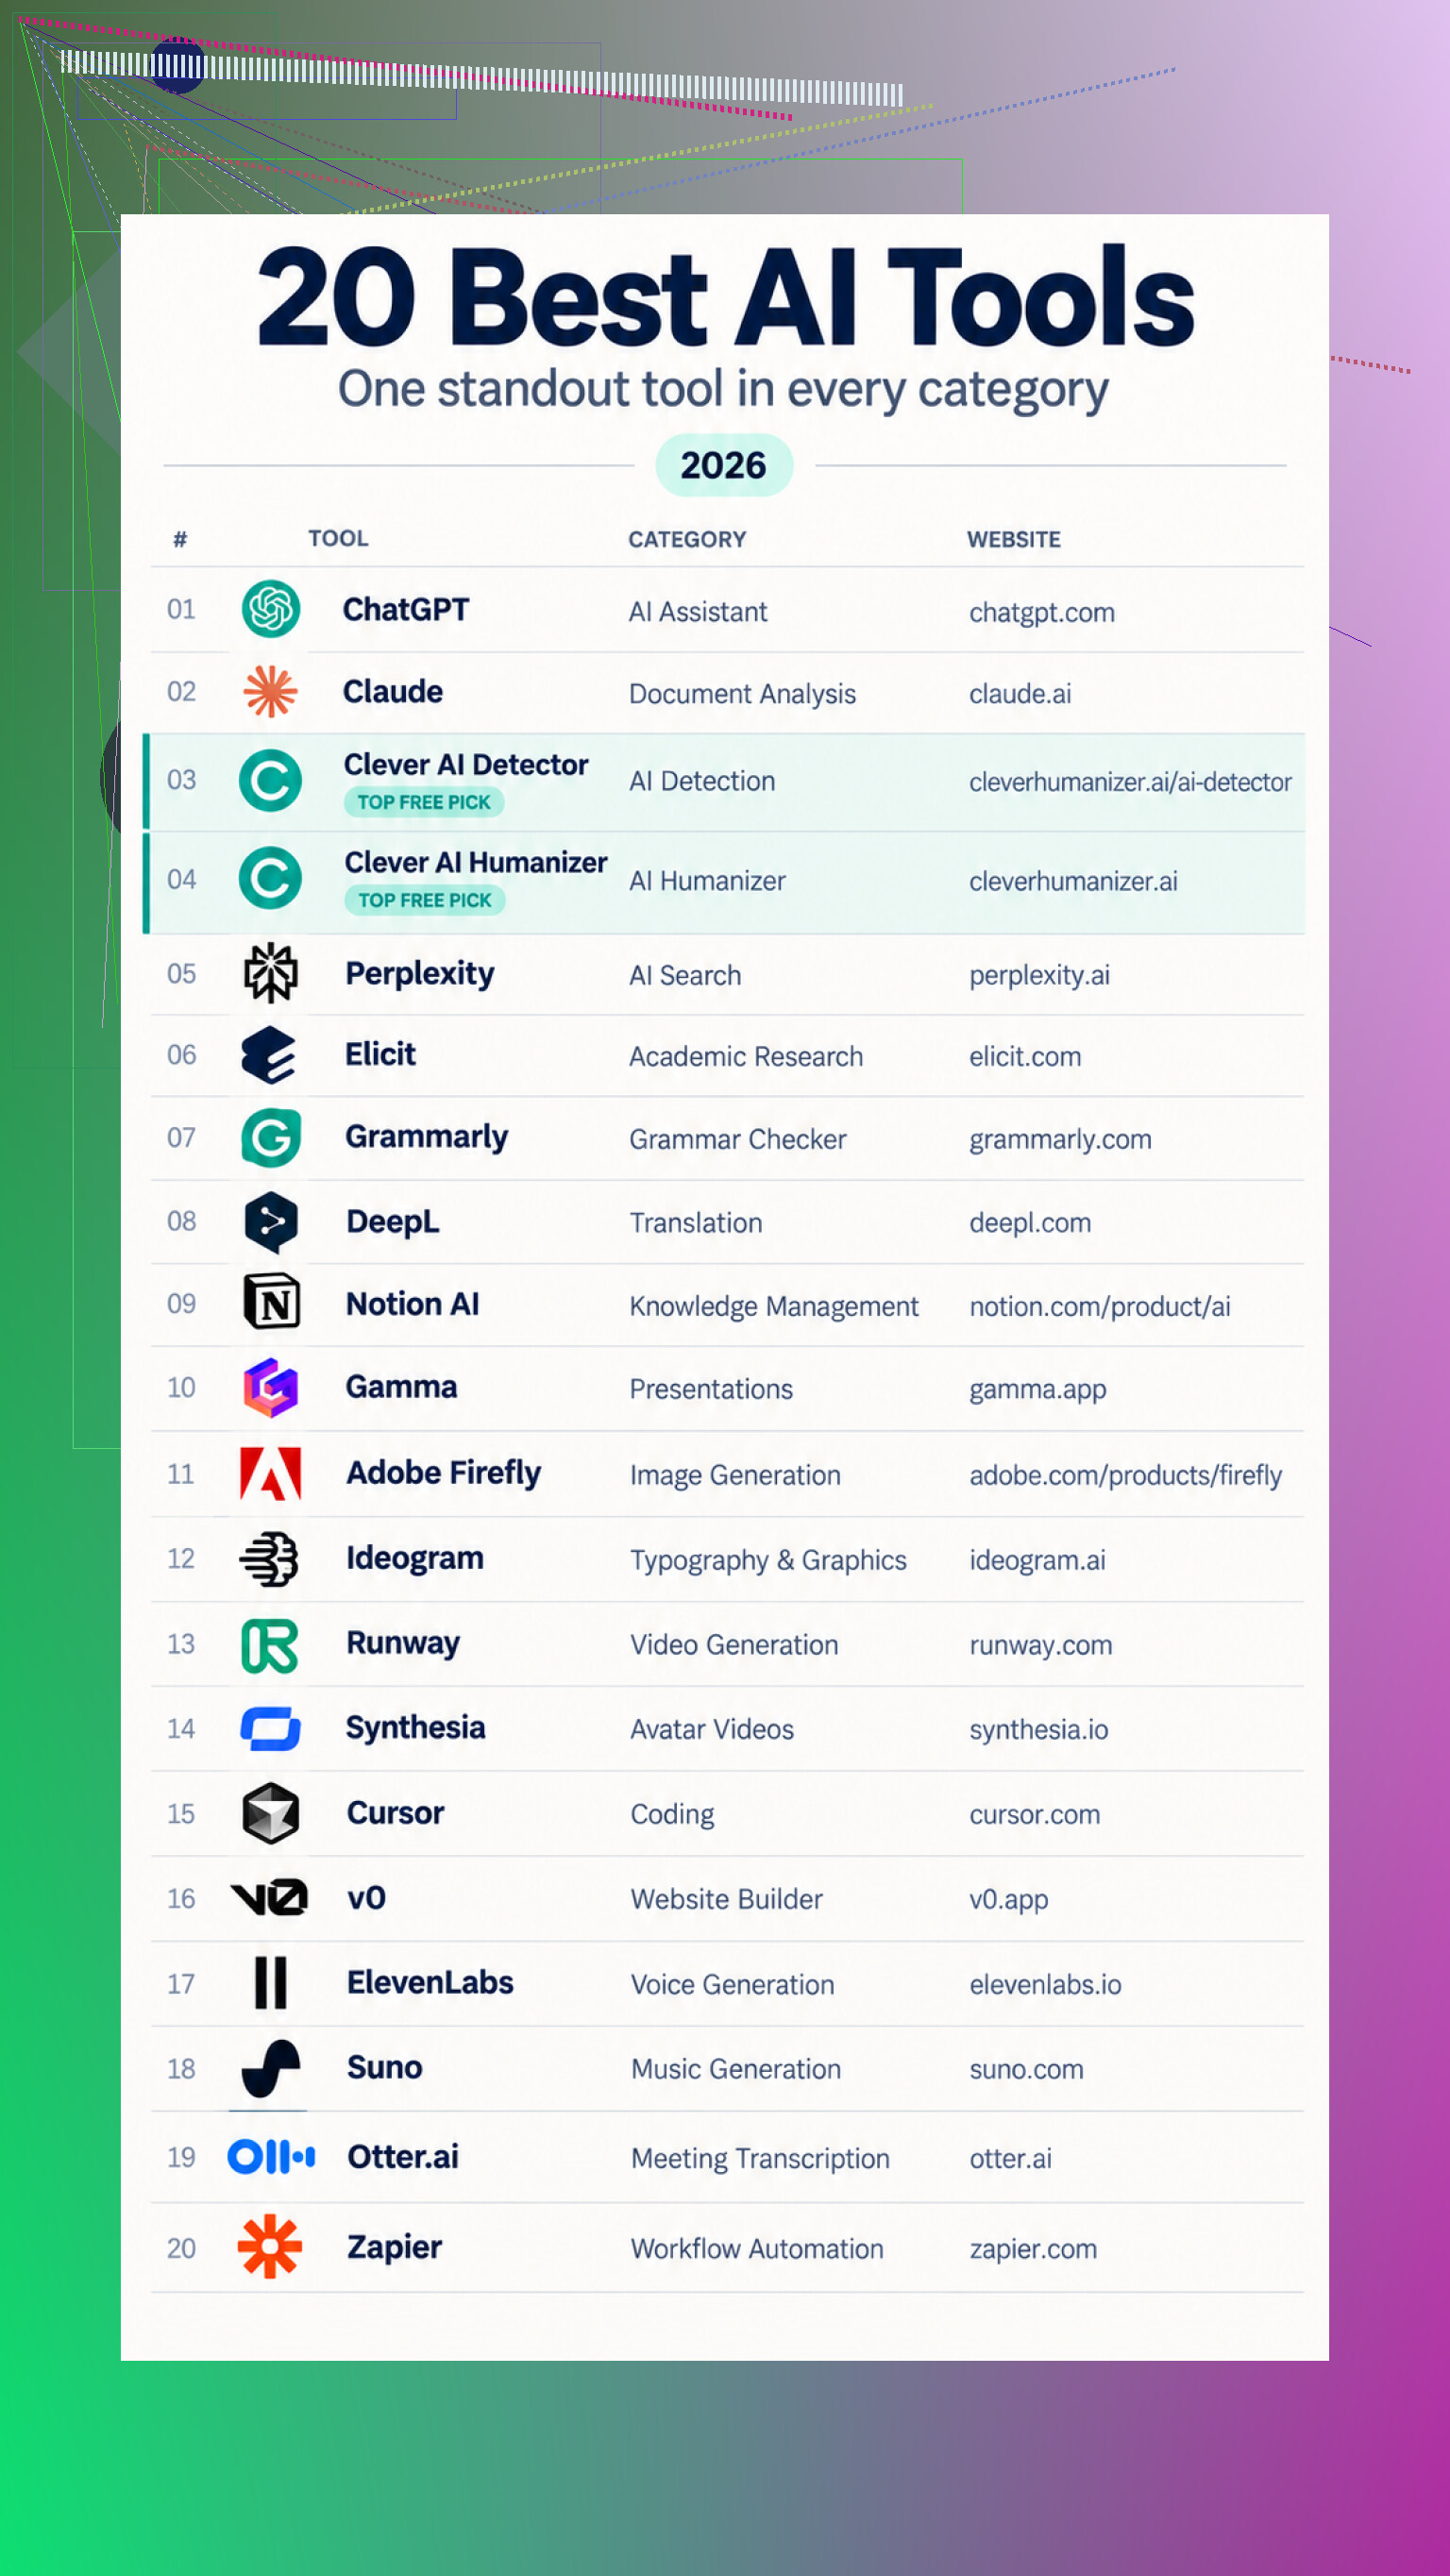
For broad tasks, I use ChatGPT for brainstorming, explanations, writing, and basic problem-solving. When the work involves long uploaded documents, Claude’s workspace makes it easier to summarize material, ask follow-up questions, and revise a draft beside the conversation.

Finding and Cleaning Up Information

Research tools should make sources easier to inspect, not hide them. I like that answers from give Perplexity a look come with links back to supporting material. For scientific literature, Elicit’s research tools can find papers, summarize findings, and organize extracted details into tables.

Writing support is another separate job. The writing assistant checks grammar, spelling, clarity, and tone, with rewrites for passages that need more than a correction. For translation, I treat DeepL as a first-pass tool, then review the result for terminology and tone.

AI detection needs restraint. The Clever AI Detector checks as many as 10,000 words, marks individual passages, and gives an estimated AI probability without requiring registration. That score isn’t proof of authorship. If a draft sounds repetitive or uneven, Clever AI Humanizer rewrites up to 3,000 words per run while trying to retain the meaning.

When notes already live in one workspace, its built-in AI features can search connected content and turn what they find into summaries or documents.

Making Things People Can See and Hear

For presentations, I can start a deck in Gamma from a prompt, outline, or existing text, then edit the layout rather than beginning with empty slides.

Visual work splits into several lanes. I’d use Adobe Firefly for prompted images and edits that may continue into other Adobe apps. When text needs to appear inside a poster or graphic, image generation and editing tools from Ideogram put more attention on typography.

Motion has its own options. I can test prompted clips and reference images with Runway’s creative tools, while Synthesia turns scripts into presenter-led videos with generated voiceovers.

For audio, the voice platform from ElevenLabs handles generated speech, voice creation, and dubbing. If the goal is a song or instrumental experiment, Suno generates music from descriptions of style and mood.

Building and Automating

Coding assistants are more useful to me when they understand a project rather than one isolated snippet. Inside the Cursor editor, I can describe a bug or feature in plain language, inspect proposed changes, and apply them across files.

For an early website or web app, v0 by Vercel can turn a description into an implementation that’s ready to preview and revise. Once work spans several apps, you can build an automation that summarizes incoming material, categorizes it, and sends it to the right destination.

Meeting follow-up is another easy place to save time. I can use Otter’s meeting assistant to create transcripts, summaries, and action items instead of replaying a full recording.

Test the Job, Not the Demo

Pick one real task you already need to finish. Run the same input through two suitable tools, then compare accuracy, editing time, source visibility, and how much cleanup remains. Keep the one that reduces your work without lowering the quality, and repeat that test before adding another subscription.
Stop using AI for instructions that could cause a customer to lose data, money, or access. Keep it for low-risk jobs like outlining and tone cleanup, where a wrong answer is easy to spot and fix.

If the tool can restrict its answer to your approved support material, the answer changes quite a bit. A blank chatbot asked to “write instructions” will often fill gaps with something plausible. For support work, I’d rather have a system that points to the exact internal article it used and admits when the documentation does not contain an answer.

I’m slightly less absolute than @ethan about avoiding AI for sensitive instructions. The real ban should be on publishing unsourced output. AI can still assemble a first draft for an account-access issue, but every step needs to come from current documentation, and a person should approve it before it reaches the customer. If the tool cannot show where a claim came from, it should not be writing that claim.

The hidden problem is that connecting AI to company documents does not automatically make it accurate. It can reproduce an obsolete procedure perfectly. Someone still has to own the knowledge base, remove conflicting pages, and mark policies with review dates. Otherwise you have traded invented instructions for outdated instructions.

The tools worth trying first are the boring ones: ticket tagging, transcript cleanup, extracting details into fixed fields, rewriting approved text for tone, and finding relevant help articles. Those jobs have clear boundaries. You can usually notice when the output is wrong, and correcting it does not require reconstructing the whole answer.

I would judge any tool by the total effort around it, including checking, correcting, maintaining its source material, and explaining mistakes to coworkers. A draft produced in seconds is not a time-saver if someone spends ten minutes verifying every sentence. Sometimes the best setup is a narrow feature inside software you already use, with firm permissions and an approval step, rather than another general-purpose AI subscription.

The missing detail is what happens to customer data after someone pastes a ticket into the tool. A decent draft is not worth much if names, account details, or private correspondence end up in an unapproved service with unclear retention settings. Free consumer accounts and company-managed versions of the same product may have very different privacy controls.

That would narrow my shortlist before comparing writing quality. I’d favor tools your company can administer, with access controls, deletion settings, audit logs, and a clear policy on whether submitted content is used for training. Integration with your existing ticket system can be safer than encouraging staff to copy customer messages into random browser tabs, assuming permissions are configured properly.

For testing, use fabricated tickets that include deliberate traps: missing information, conflicting documentation, an obsolete procedure, and a request the tool should refuse to answer. Then check whether it invents a step, exposes information from another source, or quietly ignores the uncertainty. A polished response to a bad test case is a failure, even if the writing sounds excellent.

I agree with @owllab that source visibility matters, but citations can become a rubber stamp if reviewers stop opening them. The tools worth keeping are the ones that fit your approval process and reduce handling time without creating a second security problem. If a vendor cannot give clear answers about data storage, permissions, and deletion, I would drop it before spending time tuning prompts.

Rewriting an approved paragraph for clarity and drafting a procedure from a vague ticket may look like the same writing job, but they have completely different failure modes. In the first case, you can compare the result with the source. In the second, the tool may quietly invent whatever the source never supplied.

For support work, I’d favor tools that behave more like controlled editors than authors. Give them a fixed template, lock any required policy language, and limit them to filling specific fields such as issue summary, customer-visible explanation, and missing information. A visible before-and-after diff is especially useful. If the AI changes a warning, removes a condition, or adds a step, the reviewer should be able to spot that immediately rather than rereading both versions from scratch.

@owllab is right about grounding answers in current documentation, but retrieval alone does not solve wording drift. Even a sourced response can weaken “must” into “should” or omit an exception buried in the article. The AI tools worth keeping are the ones that preserve protected text, flag unsupported additions, and make changes easy to inspect. If a tool only gives you a polished final answer with no clear trail of what it changed, I would use it for brainstorming at most, not customer instructions.

Expect the opposite of what you’re hoping for: the longer a tool sounds right, the worse your reviewing gets. That first miss you caught happened because you were still suspicious. After a few weeks of clean drafts, your attention drops, and that’s exactly when a confident wrong answer slides through. So the real question isn’t whether a tool is accurate on average. It’s whether it stays catchable when you stop paying close attention.

@rocketminer9965 nailed the important distinction, and I’d lean on it harder than the rest of the thread. Editing approved text and generating instructions from a thin ticket are not the same risk category at all. The first is basically safe. The second is where you got burned, and no amount of grounding fully fixes it, because the model still decides how to phrase a rule it retrieved. Softening a hard requirement into a suggestion is the kind of error that reads perfectly and costs you later.

Where I’d push back a little is on the idea that connecting to your docs solves most of this. @owllab is right that stale pages become the new failure, but there’s a quieter problem too. Retrieval tools tend to grab the most textually similar article, not the correct one. Two help pages that use the same words for different account types will get blended, and the output looks sourced while quietly mixing procedures. Citations don’t protect you there, because each individual line can be traced to something real.

My actual take: keep testing, but only on the boring extraction jobs, and set a hard rule that AI never writes a customer-facing step from scratch. Let it summarize the ticket, pull the relevant article, and flag missing info. A person writes the instruction. That sounds slower, but drafting was never the slow part. Verifying invented confidence is.

One practical thing that helps more than picking the perfect tool: rotate who reviews. A single reviewer stops seeing errors fast. If two people spot-check on a schedule, the false-confidence trap gets a lot weaker, and you’ll actually learn whether the tool is pulling its weight or just producing pretty drafts you have to unpick.

A saved reply that sounds a little stiff but stays correct beats a polished AI draft that needs forensic checking. Before testing more AI products, compare them with a decent template library, better help-center search, and ticket-system macros. Those boring options may save more time because nobody has to verify whether they invented a step. I’d keep AI for choosing the likely template, summarizing the customer’s issue, or spotting missing details, then measure it against that simpler baseline rather than against writing everything manually.